Behind the Headlines
Every semiconductor announcement has two stories — the one on the surface, and the real story grounded in physical evidence, market data, and 35 years of reverse engineering. This is where you find the second one.
AI infrastructure, custom silicon
Three stories about the AI buildout's less-examined layers. The real capex story is increasingly about power and packaging, not just compute; Meta just made the most contrarian infrastructure bet of any major hyperscaler; and the chiplet marketplace everyone's been promised still isn't close to existing, even as the underlying cost and yield math has already been proven.
AI Capex Headlines Are Measuring the Wrong Bottleneck.
Industry trackers confirm semiconductor capital expenditure has entered a genuine supercycle, with unprecedented spending directed at new fabs and upgraded facilities to support advanced-node manufacturing, AI accelerators, networking chips, and high-bandwidth memory, alongside increased outlays for NAND storage and advanced packaging.
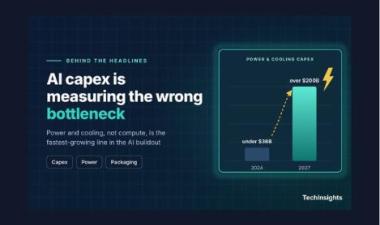
The headline capex number is real, but it's concentrating in a place most coverage undersells: power and cooling infrastructure, not compute silicon itself. Total hyperscaler datacenter capex is on pace to exceed $1.1 trillion by 2027, growing at roughly 30% annually through the back half of the decade. But the power and cooling line within that spend is growing even faster, climbing from under $36 billion in 2024 to over $200 billion by 2027 as AI rack power density keeps climbing generation over generation. That's the less-discussed half of the supercycle story: building enough compute capacity increasingly means building enough electricity and thermal management capacity first, a constraint this newsletter has flagged before as the AI buildout's real bottleneck. The packaging side of the supercycle is equally structural. GPU packaging is undergoing a hard pivot from 2D to 3D and hybrid-bonded architectures, with 3D packaging forecast to represent roughly 76% of GPU packaging units by 2027, up from just 25% in 2024 — a shift that's pulling capex toward an entirely different set of equipment and process capabilities than a simple “more fabs” narrative implies. Meanwhile, the competitive landscape within AI silicon itself is bifurcating: custom ASIC silicon from hyperscalers is capturing a rapidly growing share of rack deployments, with Google's TPU program alone forecast to ship more units than any single vendor by 2027, even as NVIDIA's own merchant GPUs and newer ASIC products expand in parallel. For any executive reading capex headlines as a simple proxy for “more chips coming,” the practical correction is to disaggregate the number. How much of a competitor's or supplier's capex growth is actually compute versus power infrastructure versus packaging retooling determines very different things about where margin, bottlenecks, and competitive advantage will actually show up over the next two years.
Market Data: Datacenter CAPEX and Servers and Data Center Processor Packaging provide the full capex and packaging forecast detail. These reports may require a paid TechInsights Platform subscription.
Meta Just Made the Strangest Bet in Hyperscaler History: Betting Against Its Own Custom Chip.
At OCP 2026, Meta detailed how it's connecting owned, leased, and public cloud infrastructure to support gigawatt-scale AI training, with coverage framing the disclosure as a straightforward hybrid infrastructure strategy consistent with how other hyperscalers are scaling AI compute.
The more surprising detail is what Meta chose not to build. Every other major hyperscaler has doubled down on proprietary training silicon — Google's TPU program, Amazon's Trainium, Microsoft's Maia — as a core pillar of AI infrastructure strategy. Meta scrapped its own Olympus training ASIC and abandoned plans for a training-capable successor to its MTIA accelerator line, instead committing to the largest merchant-silicon procurement deal in the industry: a five-year, $100-billion-plus agreement with AMD covering up to 6 gigawatts of Instinct GPU deployments, with a performance-based warrant structure that could give Meta up to 160 million AMD shares. That's a genuinely contrarian bet relative to every peer's playbook, and it makes Meta structurally more exposed to merchant-silicon pricing cycles than Google, Amazon, or Microsoft — but also more flexible, carrying none of the sunk engineering cost or roadmap lock-in that comes with a custom training chip nobody else uses. Meta's MTIA silicon hasn't disappeared; it's been deliberately repositioned to handle only inference and recommendation workloads, where TCO optimization matters more than peak training performance, while actual frontier model training runs on NVIDIA and now AMD merchant GPUs. The financing side of the strategy is just as unconventional: Meta's joint venture with BlackRock for a 1-gigawatt campus in El Paso, where BlackRock-managed funds hold an 80% stake and Meta retains just 20%, lets Meta secure massive capacity commitments without the full capex hit showing up on its own balance sheet. It’s a financing pattern that, if other hyperscalers replicate it, could make reported capex figures an increasingly unreliable proxy for actual compute capacity being built. For executives tracking hyperscaler infrastructure strategy, Meta's approach is the one worth watching most closely because it's the outlier: betting on merchant silicon flexibility over custom silicon control is a real strategic divergence, not a minor implementation detail.
Microprocessor Report: July 2026 Review and Chip Observer: March 2026 provide deeper context on Meta's infrastructure strategy. These reports may require a paid TechInsights Platform subscription.
The Chiplet Marketplace Everyone Promised Still Doesn't Exist.
Industry analysis confirms chiplet-based architectures are accelerating as semiconductor design costs escalate and advanced process nodes become increasingly complex, with disaggregated, modular designs increasingly framed as the clear future of high-performance chip design, reducing development risk while unlocking new performance and cost advantages.
The engineering case for chiplets is genuinely proven at this point — AMD's own cost data shows splitting a 16-core design across two 8-core chiplets saves roughly 12% on final tested die cost compared with a monolithic equivalent. For server-class parts scaling to 16 chiplets, costs remain roughly linear per chiplet, whereas a monolithic alternative would see costs escalate sharply as yield falls and die area grows past the reticle limit. What hasn't arrived yet, despite years of promotion, is the “plug-and-play chiplet marketplace” vision — buying compute, memory, and I/O chiplets from different vendors and combining them like licensed IP blocks. Industry consensus from the 2025 Chiplet Summit was notably blunt on why: interconnect standards like UCIe have made real progress and are no longer the primary bottleneck, but a much larger gap remains in test, reliability, thermal, and EDA standards that haven't caught up. The deeper structural issue is that a chiplet is a physical good, not an abstract design file — it carries tolerance stack-ups, early-life failure risk, and thermal and mechanical integration requirements that a GDS mask or a block of Verilog simply doesn't have to deal with, and standardizing communication protocols alone doesn't solve any of that. There's also a yield math problem that gets less attention than it deserves: individual chiplet yield gains partially reverse at the package level, since yield losses compound multiplicatively across a multi-chiplet assembly; a defect rate that looks acceptable for one chiplet can become a meaningfully worse final-assembly yield once ten chiplets are stacked together, and all the packaging cost already sunk into that assembly is wasted when one component fails. For executives evaluating chiplet strategy, the practical distinction to hold onto is that the cost and yield benefits are real and already proven in production today, chiefly within a single vendor's own portfolio, while the open, mix-and-match marketplace vision remains years away, gated by standards work that's barely started rather than by anything close to completion.
Insight: The Chiplet Reckoning — Marketplace Promise Meets Physical Reality and Insight: AMD's Chiplet Cost Math — What Splitting a Die Actually Saves go deeper on the cost, yield, and standards landscape. These reports may require a paid TechInsights Platform subscription.
Image sensors, custom silicon, advanced packaging
Three engineering stories, three cases where the smart move looked, at first glance, like a limitation. Huawei's debut sensor chose a forgiving product category over a flagship showcase, Microsoft built a chip deliberately too specialized for outsiders to want, and Huawei's packaging team turned an export-control constraint into a genuinely creative density workaround.
Huawei's First Homegrown Camera Sensor Debuted in an Action Camera. That's the Smart Part.
HiSilicon's first self-developed CMOS image sensor, the CS5250, has been confirmed via teardown inside the Xiaotu S7PRO MAX action camera, with coverage framing the device as a milestone that presents a major challenge to established image sensor leaders like Sony.
The milestone is real, but the specific product choice and the measured specifications both complicate the “major challenge” framing. At a 1.20-micron pixel pitch, the CS5250 sits in the middle of the current competitive field — denser than OmniVision's recent OV50X at 1.6 microns, but well behind Samsung's leading-edge JN3 sensor at 0.70 microns. This puts HiSilicon's debut part in a solidly competent rather than class-leading position on the metric that most directly drives smartphone camera competition. The choice of debut product matters just as much as the specs: an action camera is a meaningfully lower-stakes venue than a flagship smartphone, where sensor performance gets compared directly against established leaders under far more public scrutiny. That reads less like an announcement of parity with Sony and more like a deliberate, lower-risk venue to validate a first-generation in-house design before it appears in a product where failure would be costly and visible. There's an interesting wrinkle underneath all of this too: TechInsights' own reverse-engineering work can't yet confirm which foundry actually manufactured the CS5250, reflecting a broader opacity across Chinese image sensor supply chains that makes forensic attribution harder than it is for Western-fabricated parts. For competitors and customers in the imaging supply chain, the more useful read isn't whether HiSilicon has “caught up” — it's that debuting conservatively, in a forgiving product category, is exactly the strategy a company serious about iterating toward genuine competitiveness would choose.
Image Sensing Through the China Fog goes deeper on the supply-chain opacity behind Chinese-made image sensors. This report may require a paid TechInsights Platform subscription.
Microsoft Built an AI Chip Nobody Else Would Want. That's the Point.
Microsoft detailed its third-generation Maia AI accelerator, emphasizing aggressive support for low-precision data types, including sub-3-bit storage formats, for bulk inference workloads — with coverage noting that, unlike Google's TPUs or Amazon's Trainium chips, Maia is not available to external cloud customers as a programmable resource.
The lack of external access reads, on the surface, like a competitive weakness relative to Google and Amazon's customer-facing custom silicon programs. It's actually a deliberate and fairly logical choice once you look at what Maia 300 is optimized for. Microsoft's low-precision strategy is more aggressive than any competitor's: Maia 300 supports standard formats down to FP4, plus unusual sub-3-bit storage formats tied to Microsoft's own 1.58-bit “BitNet” research, a specialization that only pays off for models specifically designed around that level of quantization. Most external developers running typical FP8 or BF16 models wouldn't see any meaningful advantage from Maia's silicon over a standard GPU instance, which is precisely why opening it up to external customers wouldn't generate much actual demand even if Microsoft wanted to. Maia's entire value proposition is Microsoft's own proprietary inference-as-a-service economics — powering internal workloads like Copilot at a cost-per-token advantage that depends on Microsoft's own specific, ultra-low-precision model architectures, not on offering general-purpose flexibility to third parties. For competitors and partners sizing up the custom-silicon landscape, the useful distinction is that Google's TPU and Amazon's Trainium are built to be broadly useful compute products in their own right, while Maia is closer to an internal cost-optimization tool that happens to be a chip — a different kind of asset, built to solve a different kind of problem, and not a weaker version of the same strategy.
Microprocessor Report: Microsoft Maia 300 Engineering Deep Dive and Microprocessor Report: AWS Trainium3 Engineering Deep Dive provide the full competitive and architectural comparison. These reports may require a paid TechInsights Platform subscription.
Huawei Turned a Lithography Ban Into a 3D Packaging Breakthrough.
HiSilicon's Kirin 9050 Pro, powering Huawei's Mate XT 2 Ultimate tri-fold smartphone, introduces “LogicFolding,” a 3D die-stacking architecture that Huawei describes as shortening electrical paths and maximizing transistor density without relying on EUV lithography.
The EUV caveat in Huawei's own framing is the whole story. Export controls have cut Huawei and its foundry partner SMIC off from the extreme ultraviolet lithography tools needed to shrink transistors at the pace TSMC and Samsung can, so conventional node-shrink scaling — the default way every other chipmaker increases density — simply isn't fully available to them. LogicFolding is a genuinely creative structural workaround: rather than packing more transistors into a smaller area through finer lithography, HiSilicon split a single logic design across two SMIC process nodes on two separate dies, hybrid-bonded face-to-face at a confirmed 1.5-micron pitch carrying roughly 50 million vertical connections, and stacked them to recover density through 3D integration instead. The underlying engineering logic holds up: since data movement, not transistor switching, dominates dynamic power consumption in modern logic, shortening the physical distance between circuit blocks through vertical stacking delivers real efficiency gains even without a smaller transistor. The approach isn't free of trade-offs — stacking concentrates heat in ways that demand careful floorplanning, placing high-power blocks opposite low-power ones to avoid compounding hotspots, and SMIC's underlying N+3 process itself is independently assessed as roughly comparable to a 6-nanometer-class node rather than genuine leading-edge density. For executives tracking China's semiconductor self-sufficiency trajectory, LogicFolding is a concrete data point that export controls are generating real architectural innovation rather than simply stalling progress outright — a different kind of competitive risk than assuming controls have fully contained China's chip design capability.
2026 Compute Advanced Packaging Briefing 2 and 2026 Compute Process Technology Briefing 2 provide the full LogicFolding and SMIC N+3 technical detail. These reports may require a paid TechInsights Platform subscription.
Battery supply, fab utilization
Two procurement stories, two reminders that the real constraint is rarely the one getting discussed. Europe's 800V timeline is gated by cell-chemistry sourcing decisions made years ago, not current engineering speed, and a humble rubber seal may tell you more about real fab utilization than any capex headline will.
Europe Is Showing 800V Concept Cars. China Already Built the Supply Chain for Them.
At the Paris Motor Show 2026, Chinese automakers showcased 800V vehicle platforms already shipping at volume, while European manufacturers largely presented 800V concept vehicles rather than production models, with coverage framing the contrast as a familiar story of China's faster EV execution speed.
The execution-speed framing undersells a deeper structural constraint: Europe's concept-only showing reflects a genuine cell-supply mismatch, not simply a slower product-development pace. China's battery cell manufacturing capacity runs roughly 7.5 times larger than Europe's, and crucially, a meaningful share of that Chinese capacity was purpose-built for 800V chemistries and formats from the start — CATL's Wuhan facility, for instance, was explicitly designed for 800V applications and already supplies Xpeng's G9 platform. European and North American automotive programs, by contrast, remain largely dependent on Korean-supplied cell formats engineered around the legacy 400V architecture that's dominated EVs for most of the last decade, meaning a European OEM wanting to ship 800V platforms at real volume faces a cell-sourcing problem that a faster design studio can't solve on its own. That gap widened further when Northvolt, Europe's primary independent, non-Chinese cell supplier, filed for bankruptcy in 2025, with its remaining assets acquired by Lyten — leaving European automakers more dependent than before on Korean and Chinese-origin suppliers for any near-term cell sourcing, 800V or otherwise. The semiconductor angle compounds the timeline: 800V architecture requires silicon carbide power devices to handle the higher bus voltage efficiently, and automotive SiC revenue is forecast to grow at roughly 22% annually through 2031 as 800V adoption scales — meaning the same cell-supply bottleneck constraining European platforms is also constraining the SiC demand ramp tied to them. For procurement and supply-chain executives, the practical takeaway is that Europe's 800V timeline is gated by cell-chemistry sourcing decisions made years ago, not by current engineering capability, and closing that gap requires multi-year capacity commitments rather than a faster next product cycle.
Power SiC Market Share & Forecast and Battery Technology Manufacturing Capacity Forecast provide the full cell-capacity and SiC demand detail. These reports may require a paid TechInsights Platform subscription.
The Best Leading Indicator for Fab Activity Might Be a Rubber Seal.
A technical session at Semicon West examined demand for FKM and FFKM elastomer seals used in semiconductor manufacturing equipment, with coverage framing the presentation mainly as a niche materials-market forecast relevant primarily to chemical and component suppliers rather than to broader semiconductor industry planning.
The niche framing misses why this specific, unglamorous component category is actually a useful leading indicator for something much bigger: real fab utilization, as distinct from announced fab capacity. FFKM seals are consumable parts inside plasma etch, CVD, and ion implant chambers, replaced on a maintenance cycle directly tied to how much those chambers are actually running — not how much capacity a fab has on paper, but how hard that capacity is actually being used. That distinction matters because headline capex and announced capacity numbers, the figures most executives actually track, say nothing about utilization, while consumable replacement demand for parts like these responds almost immediately to real changes in fab activity. The seal market itself is dominated by FFKM chemistry, reflecting its chemical-inertness requirements in the most aggressive process steps, and growth is overwhelmingly tied to semiconductor manufacturing rather than adjacent markets like flat-panel displays or photovoltaic production, both of which are flat to declining. For executives trying to read the real state of the chip-manufacturing cycle — whether capacity additions are translating into genuine utilization or sitting partially idle — a category like elastomer seal consumption offers a more honest, higher-frequency signal than capex announcements or even reported utilization rates, since it reflects actual chamber-hours rather than self-reported figures. The practical application for procurement and supply-chain planning teams goes beyond simply tracking this one market: it's a reminder that demand for consumables and maintenance parts, broadly, tends to be a more reliable real-time proxy for what's actually happening inside a fab than any top-line capacity or spending figure.
Critical Subsystems Graphics and Performance Indicators tracks fab utilization by wafer size and technology node, providing the broader utilization context behind this seal-demand signal. This report may require a paid TechInsights Platform subscription.
Every semiconductor announcement has two stories.
Register with your corporate email address for full access to TechInsights research.
Register here